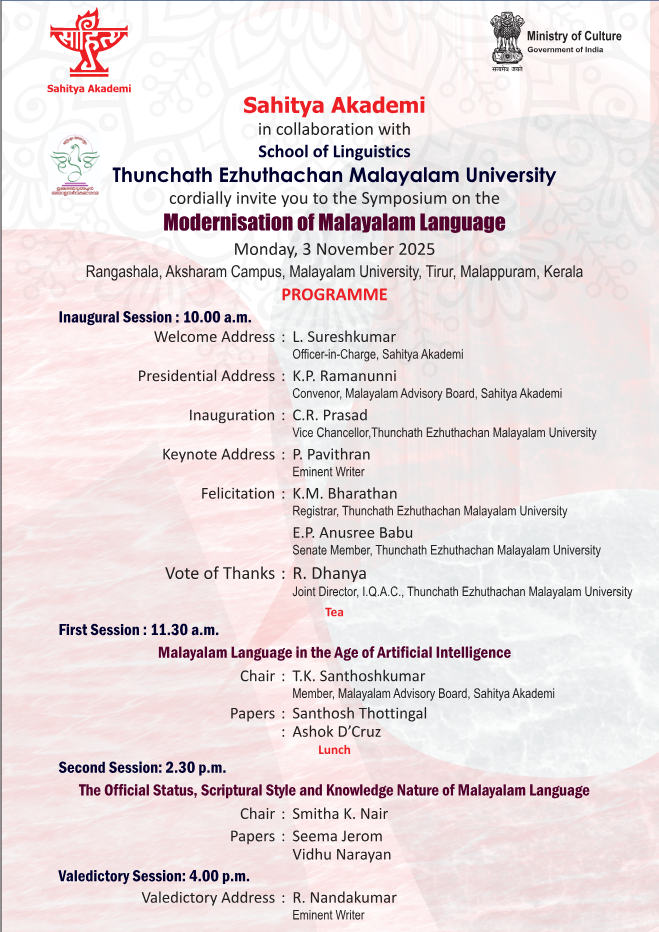
On November 3rd, I spoke at Malayalam University on “How AI learns Malayalam,” tracing how humans acquire language versus how Large Language Models learn from patterns at scale.
This invited session was part of Symbosium on modernization of Malayalam language, organized by Sahitya Akademi and Malayalam University.
Using Chomsky’s Syntactic Structures and the “colorless green ideas” example to frame structure vs. meaning, I contrasted innate rules with data-driven learning, engaged Emily M. Bender et al.’s “Stochastic Parrots” critique of ungrounded fluency, and reflected on Richard Sutton’s “Bitter Lesson” and his call for world models - asking what written text alone can and cannot teach machines. To contrast meaning and Syntax, I used a scene from 1985 Malayalam movie “Boeing Boeing” (..ഇനിയും വരില്ലേ ആനകളേയും തെളിച്ചുകൊണ്ട്.. 😃 )

Grounding that debate in Malayalam, I walked through Zipf’s law in our corpora, simple Markov chains (Andrey Markov), and Zellig Harris’s distributional hypothesis as a bridge to embeddings, transformers, and attention. I demoed MLMorph for analysis/generation/spellcheck and discussed why Malayalam’s rich morphology, free word order, tokenization quirks, and limited representation in common training sets make modeling harder. I emphasized that existing large language models cannot provide English like features to smaller languages and require better algorithms that overcome data scarcity and language nuances.
Here is the slides I used https://santhoshtr.github.io/ai-linguistics-malayalam-talk/. Note that it does not cover what I talked, it has the narration flow and visuals.